A server’s data lives in a database, and this chapter is about reaching it: the connection pool, which speaks to SQLite, PostgreSQL and MySQL with one dialect of SQL, the object mapping the build generates daos from, and the transactions that make several statements one unit of work. The last of those gets the most room, because declarative transactions are where a Spring developer’s intuitions are most likely to be almost right.
Talking to a database
The server opens a connection pool from cn1.datasource.url — a SQLite path or
a PostgreSQL or MySQL URL — and injects it as a DataSource into any bean that
asks for one. It returns rows as the same Java types whichever engine answered:
// db is the pool the server opened from cn1.datasource.url and injected
List rows = db.query("SELECT id, body FROM note WHERE id > ?",
                     new Object[] { Integer.valueOf(10) });
There is no JDBC driver involved. SQLite is linked into the binary, and the
PostgreSQL and MySQL clients speak their wire protocols directly, and a
mariadb:// URL is served by the same client. MySQL 8.0 and MariaDB 10.4 and
newer are supported: a string key needs a case-sensitive NO PAD collation, so
"A" and "a" are two keys and "token " keeps its space, and the two server
families spell that collation differently. Which one is used comes from the
server rather than from the URL scheme, so a mysql:// URL pointed at MariaDB
is still correct.
Statements are written once, in one portable form: ? for every parameter, and
plain unquoted names. PostgreSQL binds $1 rather than ?, and that difference
stops inside execute and query rather than at every call site. SQL already
written for one engine keeps working, because a statement carrying no ? at all
is passed through untouched — so hand-written $1 is left alone. A literal
question mark that isn’t a parameter is written ??, which matters on
PostgreSQL, whose jsonb operators are spelled ?, ?| and ?&.
A parameter count that doesn’t match the statement is refused before the statement is sent. The three engines answer a mismatch three different ways, and SQLite’s answer is to bind the missing parameters to NULL and commit the row.
The other thing the engines disagree about is the key an insert generated.
insert asks whichever way this engine answers — last_insert_rowid() on
SQLite, LAST_INSERT_ID() on MySQL, and INSERT … RETURNING on PostgreSQL,
which has no last-insert-id concept at all:
long id = db.insert("INSERT INTO note (body) VALUES (?)",
                    new Object[] { "first" }, "id");
Several statements that have to be one go through inTransaction, which holds a
single connection for the whole body and rolls back if it throws:
db.inTransaction(new DataSource.Work() {
    public Object run(Database connection) throws Exception {
        connection.execute("UPDATE account SET balance = balance - ? WHERE id = ?",
                           new Object[] { Integer.valueOf(100), Integer.valueOf(1) });
        connection.execute("UPDATE account SET balance = balance + ? WHERE id = ?",
                           new Object[] { Integer.valueOf(100), Integer.valueOf(2) });
        return null;
    }
});
Everything each engine spells differently is reachable through db.dialect(),
which is what code that generates schema needs:
Dialect dialect = db.dialect();
String create = "CREATE TABLE IF NOT EXISTS " + dialect.quote("note") + " ("
        + dialect.quote("id") + " " + dialect.generatedKeyColumn(Dialect.BIGINT) + ", "
        + dialect.quote("body") + " " + dialect.columnType(Dialect.TEXT) + ")";
Quoting every identifier isn’t caution. PostgreSQL folds an unquoted name to
lower case while SQLite and MySQL preserve it, so a column called createdAt
becomes createdat on one engine of the three, and code that reads rows by name
stops finding it there.
A Database — one connection rather than a pool — is still available through
Database.open for code that wants exactly one, and every one of its operations
is synchronized, so sharing one across handlers is safe and serialized. That’s the
right shape for a single-file SQLite server and the wrong one for a database
that’s a machine across a network: there the single connection isn’t a safety
property, it’s the bottleneck. The pool is the default for that reason.
Storing objects
A class with @Entity on it gets a data access object written for it at build
time. The annotations are the ones the SQLite ORM chapter documents, and they
are the same annotations in the same package, because an entity is the one class
both halves of an application own:
@Entity(table = "reminders")
public class Reminder {
    @Id public long id;

    @Column(nullable = false) public String title;

    public java.util.Date due;

    public boolean done;

    @DbTransient public String cachedLabel;   // never stored

    public Reminder() {
    }
}
What differs between the app’s copy and the server’s is what the build generates from it: a module compiled against the Codename One core gets a dao over the local SQLite database, and a module compiled against this runtime gets one whose statements are built for whichever engine the connection turns out to be. The class says what the data is; the module says where its rows live.
Dao<Reminder> reminders = em.dao(Reminder.class);

Reminder reminder = new Reminder();
reminder.title = "renew the certificate";
reminder.due = new Date();
reminders.insert(reminder);          // reminder.id is now the generated key

Reminder stored = reminders.findById(Long.valueOf(reminder.id));
stored.done = true;
reminders.update(stored);
The entity manager comes from the entry point, which opens one when the build generated at least one entity. A controller asks for it by declaring a constructor that takes one, and the generated entry point calls that constructor:
@RestController
@RequestMapping("/reminders")
public class ReminderApi {
    private final Dao<Reminder> reminders;

    /** The entry point calls this one because it is the one declared. */
    public ReminderApi(EntityManager entities) {
        this.reminders = entities.dao(Reminder.class);
    }

    @GetMapping
    public List<Reminder> outstanding() throws IOException {
        return reminders.query().eq("done", Boolean.FALSE).orderBy("due", true).list();
    }
}
A controller is a bean, so its constructor can take the entity manager, the pool,
or any service built on them, as Backend beans and dependency injection describes. The generated entry
point holds a new with the argument written into it, and a controller that needs
a database nothing configured is refused at start-up rather than handed a null to
fail on later.
The build writes the entry point, and the daos are registered there: this
runtime has no reflection and the translator drops a class nothing references,
so the generated code’s direct reference to every dao is what keeps them in the
binary. Put start-up work in a bean’s @PostConstruct method.
Outside the server — in a unit test, say — an entity manager is a single call over a pool:
EntityManager em = EntityManager.open(pool);
Queries name JAVA FIELDS rather than columns, and the builder quotes the column each one maps to:
List<Reminder> overdue = em.dao(Reminder.class).query()
        .eq("done", Boolean.FALSE)
        .lt("due", new Date())
        .orderBy("due", true)
        .limit(20)
        .list();
A name that isn’t a field of the entity is refused at once, listing the
ones that are, rather than reaching the server as a column it doesn’t have.
eq, ne, gt, gte, lt, lte, like, in, isNull and isNotNull are
joined with AND in the order they were added, and list, first, count and
delete end the chain. A query the builder can’t express takes SQL instead,
through dao.find(where, params), which is the point at which portability
becomes yours to keep.
Transactions take the same shape as everywhere else: the entity manager the body
is handed is pinned to one connection, so every dao reached through it runs inside
the transaction. Called inside a @Transactional method, it joins that
transaction instead of starting another.
em.transaction(new EntityManager.Work() {
    public Object run(EntityManager tx) throws Exception {
        Dao<Reminder> reminders = tx.dao(Reminder.class);
        Reminder first = reminders.findById(Long.valueOf(1));
        first.done = true;
        reminders.update(first);
        reminders.insert(follower(first));
        return null;
    }
});
Three things this doesn’t do, on purpose. Relationships aren’t supported — @OneToMany and friends don’t exist, and a field referencing another entity
fails the build with a message saying to persist the foreign key as a scalar.
createTable creates a table that isn’t there and does nothing at all to one
that is, so it’s a convenience for development and for tests rather than a
migration tool. And a boolean, a date and a char are stored as integers on every
engine — 0 or 1, epoch milliseconds, and the UTF-16 code unit — because a
native timestamp comes back as text whose format follows the server’s own time
zone and would not round-trip the same way on three engines, and because a char
that was never assigned holds NUL, which PostgreSQL refuses inside a text value.
A field declared as a primitive gets a NOT NULL column, because a primitive has
no null to read: a nullable column would load as 0, false or \0, which is
indistinguishable from a row that holds those. Declare the field as its boxed
type — Integer rather than int — when the column can be empty.
Transactions
A transaction makes several statements succeed or fail together. @Transactional
declares one around a method, and the build writes the code that begins, commits
and rolls back the transaction around the method’s body:
@Transactional(rollbackFor = IOException.class)
public void register(String email) throws IOException {
    db.execute("INSERT INTO signup (email) VALUES (?)", new Object[] {email});
    // Throws when the mail server refuses: the insert above is rolled back,
    // because both run in the one transaction this method began. A failed
    // statement would roll back on its own -- it is a DataAccessException --
    // but the mailer's IOException is checked, so it takes rollbackFor.
    mailer.send(email, "Welcome", "Thanks for signing up.");
}
Everything the method does through the server’s DataSource joins the
transaction without being handed anything, and so does every method it calls on
the same thread. On a class, @Transactional applies to each public method the
class declares. As in Spring, a method it inherits from a superclass isn’t
covered until the class overrides it, and the build warns about each one. The
same holds for @Async on a class.
How a method joins a transaction
The transaction belongs to the thread that began it. When a thread inside one
asks the pool for a connection — directly, through an entity manager’s daos, or
through a DataSource method — it gets the transaction’s connection back instead
of a pooled one. That’s why a service three calls deep takes part without a
parameter for it, and why the programmatic forms, DataSource.inTransaction and
EntityManager.transaction, run as part of an open transaction rather than
starting a second one.
The connection is borrowed, and BEGIN sent, only when the method first touches
the database. A @Transactional method that returns early, or that turns out to
have nothing to write, never takes a connection at all. The same laziness settles
which database a transaction is on: the first pool it touches. Statements through
any other pool run outside it, each committing on its own.
A transaction doesn’t follow work to another thread. An @Async method, a task
given to Tasks, or a scheduled job runs outside the caller’s transaction, and
begins its own if it’s @Transactional itself.
Propagation
propagation says what a method does when it’s called with a transaction already
open. The default, REQUIRED, is right for most methods: join the open
transaction, or begin one if there is none.
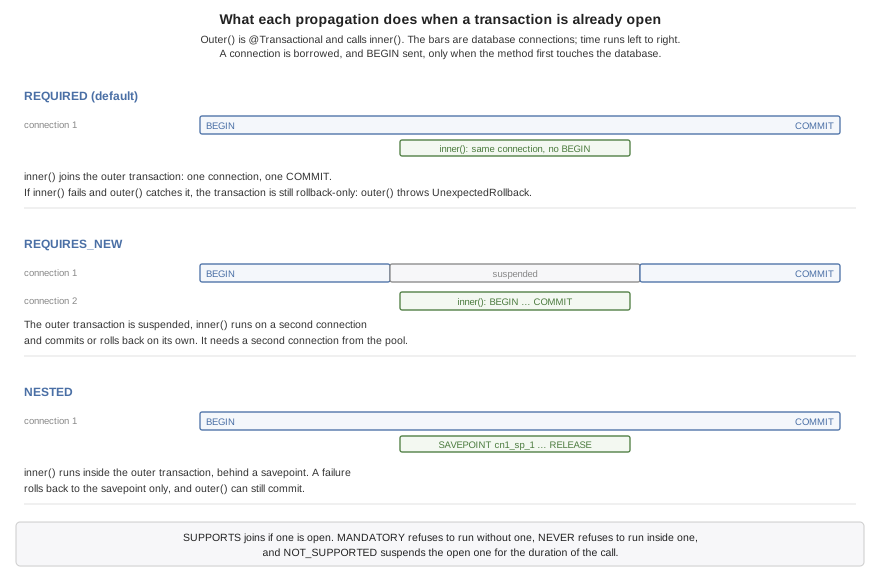
| Propagation | With a transaction open | With none open |
|---|---|---|
| Joins it. | Begins one. |
| Suspends it and begins another, on a second connection. | Begins one. |
| Sets a savepoint in it. | Begins one. |
| Joins it. | Runs without one. |
| Joins it. | Throws |
| Suspends it and runs without one. | Runs without one. |
| Throws | Runs without one. |
REQUIRES_NEW suits work that must be kept whatever happens to the caller, an
audit record being the usual case:
@Service
public class AuditLog {
    private final DataSource db;

    public AuditLog(DataSource db) {
        this.db = db;
    }

    @Transactional(propagation = Propagation.REQUIRES_NEW)
    public void record(String event) throws IOException {
        // Commits on its own connection, whatever the caller's transaction does.
        db.execute("INSERT INTO audit (event) VALUES (?)", new Object[] {event});
    }
}
It costs a second connection for as long as it runs, taken from the same pool while the first one is still held. See the pitfalls at the end of this chapter before using it on SQLite.
Rollback rules
The rules are Spring’s. An unchecked exception or an Error leaving the method
rolls the transaction back, and a checked exception commits it — with the one
addition that keeps the outcome Spring’s, described in the note below. rollbackFor
adds exception types that roll back, noRollbackFor adds types that commit, and
when several listed types match the thrown one the most specific wins. The
decision is written into the method as a chain of instanceof tests, so nothing
reads the annotation when the method runs:
@Service
public class Orders {
    private final DataSource db;
    private final AuditLog audit;

    public Orders(DataSource db, AuditLog audit) {
        this.db = db;
        this.audit = audit;
    }

    @Transactional(rollbackFor = PaymentDeclined.class, timeout = 10)
    public long place(String sku, int quantity) throws IOException, PaymentDeclined {
        long id = db.insert("INSERT INTO orders (sku, quantity) VALUES (?, ?)",
                new Object[] {sku, Integer.valueOf(quantity)}, "id");
        audit.record("order " + id + " attempted");  // kept even if this rolls back
        charge(id);                                  // may throw PaymentDeclined
        return id;
    }
In Spring, a statement that fails throws the unchecked DataAccessException, so
it rolls the transaction back. The methods of DataSource, Database and the daos
declare the checked IOException, and the failures they report — a statement the
engine refused, a connection that couldn’t be opened, a query that returned more
than one row where one was expected — are
com.codename1.backend.DataAccessException, a subclass of it. The default rule
rolls back for that type as well, so a failed statement undoes the transaction as
it would in Spring. Any other IOException — a file that couldn’t be read, a
mail server that refused a message — is checked and commits, as it would in
Spring; list it in rollbackFor to make it roll back, as the Signups example
does. noRollbackFor = DataAccessException.class restores plain commit-on-checked.
A method that joined a transaction can’t roll back what the method that began it
did before it, so when it fails with an exception that rolls back, it marks the
whole transaction rollback-only instead. The method that began the transaction
then rolls back when it ends. If it ends normally — because it caught the
exception — the rollback is reported by throwing
TransactionException.UnexpectedRollback, so the caller doesn’t take a
rolled-back transaction for a committed one.
Transactions.setRollbackOnly() undoes a transaction without an exception. Called
in the method that began the transaction, it lets that method return normally,
and the transaction rolls back without an error when the method ends. Called in a method
that joined the transaction, it counts as that method failing: the transaction
becomes rollback-only, and the method that began it throws
TransactionException.UnexpectedRollback when it ends normally. Called in a
NESTED method, it undoes only that method’s work: its savepoint is rolled back
when it returns, and the surrounding transaction carries on.
Transactions.isActive() and Transactions.isRollbackOnly() answer the obvious
questions about the calling thread.
Read-only transactions and timeouts
readOnly = true begins a transaction the engine is told only reads. PostgreSQL
and MySQL then refuse any write inside it, which turns a read path that writes by
mistake into an error. SQLite accepts the flag and enforces nothing.
timeout is in seconds, counted from the start of the method. It’s checked when
the transaction first touches the database, where a transaction already past its
limit fails with an IOException, and again at commit, where it’s rolled back and
reported with TransactionException.TimedOut. It doesn’t interrupt a statement
that’s running, so it bounds how long a transaction can take to commit rather than
how long any one query may run.
Savepoints
NESTED runs a method inside the open transaction, behind a savepoint. A failure
rolls back to the savepoint and nothing more, and the outer method can go on and
commit. That suits a batch in which one bad item shouldn’t cost the rest:
@Service
public class Imports {
    private final DataSource db;

    public Imports(DataSource db) {
        this.db = db;
    }

    @Transactional
    public int importAll(List<String> lines) {
        int imported = 0;
        for (String line : lines) {
            try {
                importLine(line);           // a call through this: still transactional
                imported++;
            } catch (Exception bad) {
                // Only this line's rows were rolled back, to its savepoint.
            }
        }
        return imported;                    // the good lines commit together
    }

    @Transactional(propagation = Propagation.NESTED)
    void importLine(String line) throws IOException {
        String[] fields = line.split(",");
        db.execute("INSERT INTO contact (name) VALUES (?)", new Object[] {fields[0]});
        db.execute("INSERT INTO phone (number) VALUES (?)", new Object[] {fields[1]});
    }
}
The loop calls importLine through this, which in Spring would bypass the
annotation entirely and run every line in the outer transaction without a
savepoint. Here the annotation is part of the method, so the call gets its
savepoint however it’s made.
The savepoints are named by the runtime and released when the method returns normally. All three engines support them.
The transaction’s session
A bean can inject com.codename1.orm.session.Session, the persistence session of
the ORM, and use it inside a transaction:
@Service
public class ReminderService {
    private final Session session;      // the current transaction's session

    public ReminderService(Session session) {
        this.session = session;
    }

    @Transactional
    public long remind(String title) {
        Reminder reminder = new Reminder();
        reminder.title = title;
        reminder.due = new Date();
        session.persist(reminder);      // written by the time the transaction commits
        return reminder.id;
    }

    @Transactional(readOnly = true)
    public Reminder find(long id) {
        return session.find(Reminder.class, Long.valueOf(id));
    }
}
The injected object stands in for the session of whichever transaction is open on
the calling thread. The session is opened on the transaction’s connection the
first time it’s used, its pending changes are flushed into the transaction before
it commits, and it’s closed when the transaction ends. A savepoint that rolls back
also clears the session, since the rows it had loaded since the savepoint no longer
exist. Used outside a transaction, it throws with a message saying to annotate the
method, or to open a session with EntityManager.openSession().
Why a call through this works
Spring applies @Transactional with a proxy: a wrapper object stands between a
caller and the bean, and the transaction happens in the wrapper. A call that
doesn’t go through the wrapper — one from the bean to itself, to a private method,
or on an object the application built with new — gets no transaction, and
nothing warns about it.
Here the build rewrites the compiled method. Its body moves to a method of its own
and the method keeps its name, now starting the transaction, calling that body,
and committing, with the rollback decision written in. The transaction is
therefore a property of the method, and every call gets it. The same rewriting
gives @Async, @Timed and @Counted the same property.
Pitfalls
Checked exceptions other than database failures commit. A failed statement rolls back, but an
IOExceptionfrom anything else — a file, a mail server, an outbound HTTP call — commits unless it’s listed inrollbackFor.REQUIRES_NEWneeds a second connection. The outer transaction keeps its connection while the inner one borrows another, so on a pool of one — the default for an in-memory SQLite database — the inner borrow waits forcn1.datasource.pool.borrowTimeoutMillisand fails.SQLite has one writer. A transaction that has written holds the database’s write lock until it ends, so a
REQUIRES_NEWmethod that writes while its caller holds the lock waitscn1.datasource.busyTimeoutMillisand fails. Reading works. On SQLite, record the audit row after the outer transaction, or in it.Transactions don’t cross threads. Work handed to
@AsyncorTasksisn’t part of the caller’s transaction and can’t see its uncommitted rows.A transaction holds a connection. From its first statement until it ends, the connection is out of the pool. An outbound HTTP call inside a transaction keeps it there for the length of the call, and enough of those at once starve the pool. Make the call before the transaction begins, or after it ends.